


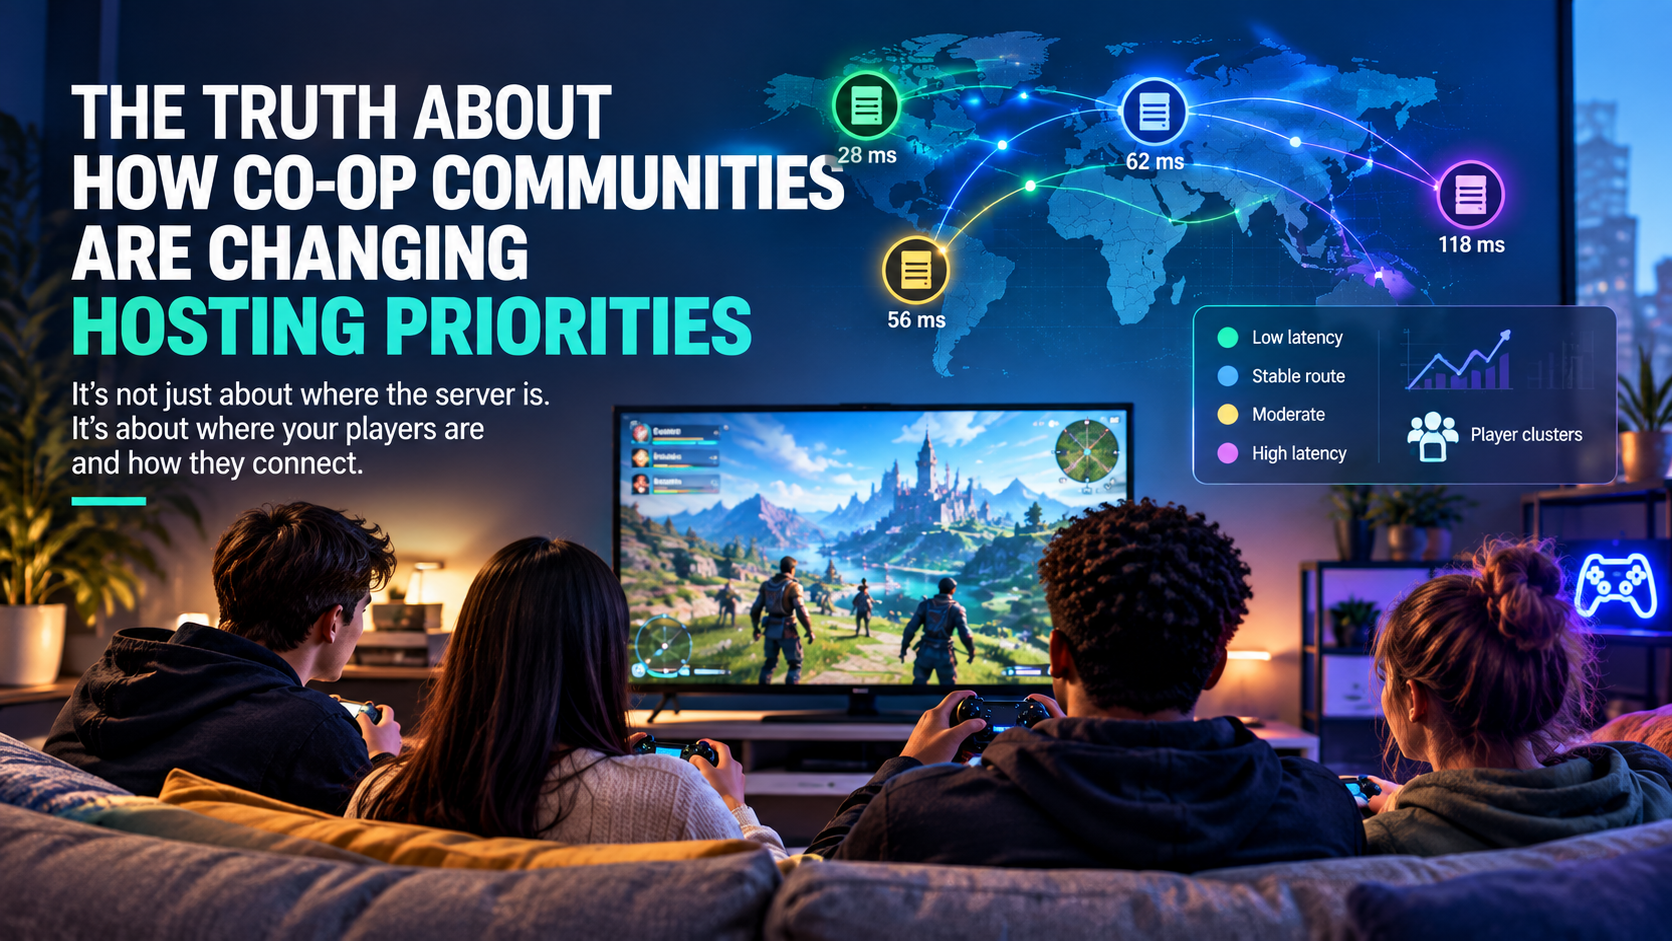

For a dispersed co-op party, the host’s hometown is not a useful shortcut for choosing a server location. A party can span several cities, countries, and time zones, so the practical target is acceptable latency for the largest share of active players.
This shifts a multiplayer community’s priorities toward observed session conditions, route quality, and placement decisions that benefit the whole group. Hosting becomes a group-quality decision rather than a choice built around one organizer’s connection. It also provides a clearer basis for infrastructure spending because organizers can invest in locations and resources supported by actual player data.
A server located close to the host may give that person an excellent connection while leaving everyone else with higher latency or unstable routes. In a four-player party, that imbalance may be inconvenient. In a larger community running scheduled events, persistent worlds, or rotating matchmaking sessions, it can affect participation and player retention.
Communities therefore need to ask different questions. Where are active players connecting from? Which locations offer the most consistent routes to those clusters? How much latency variation occurs during peak hours? And does the server maintain stable performance when the expected number of players joins?
Build a player-distribution map before choosing a location
Community organizers can start with a player-distribution map—an editorial “heat map” built from session demand, player locations, matchmaking patterns, and latency measurements.
This map should represent active participation rather than simply listing every registered member. A community might have hundreds of members across many countries, but most regular sessions may involve two or three concentrated groups. Weighting the data by actual activity makes it easier to see where low-latency capacity would benefit the most players.
Amazon GameLift Servers can collect player latency for candidate locations, while UDP ping beacons provide location-specific measurements. Over several sessions, this record reveals where demand concentrates and where routes create recurring friction.
The data should be gathered at different times because network conditions are not fixed. A route that performs well in the morning may become congested during evening hours. Weekends, game updates, tournaments, and major releases can also create demand patterns that are not visible in a one-time test.
Organizers should monitor more than average latency. Jitter shows how much latency changes during a session, while packet loss reveals whether some data fails to reach its destination. A connection that remains close to 50 ms may deliver a smoother experience than one that averages 35 ms but repeatedly spikes above 100 ms.
A PSN gift card from Eneba can remove a separate purchasing delay before a planned session, with platform and regional details visible on the product page. This helps players prepare for a scheduled game without confusing product access with server performance, which remains a separate hosting consideration.
Access planning and hosting planning solve different problems
A $100 PlayStation card is usually priced at face value, although the final cost can vary slightly depending on the retailer, taxes, region, or available discounts. Clear platform and regional listings help a group choose the appropriate product while coordinating a session.
However, a product’s region does not reveal where the game server is located or how efficiently a player’s traffic will reach it. A game or gift card can work correctly with a regional account while the multiplayer connection still follows an inefficient network route.
This distinction matters when organizing international groups. Access planning ensures that players have the right game, platform, subscription, or account-compatible product. Hosting planning determines whether the shared session will remain stable once those players connect.
Treating them as separate tasks prevents organizers from making assumptions based on broad labels such as “Europe,” “North America,” or “Asia.” Those labels may be useful for eligibility or product activation, but they provide only limited information about real network performance.
Measured routes beat geographic guesses
A map should guide the first deployment choice, not close it. A nearby city can still produce a poor route when traffic crosses distant transit paths, encounters congestion, or relies on remote peering.
Internet traffic does not necessarily travel in a direct line between the player and the server. It moves through networks operated by internet service providers, hosting companies, transit providers, and other infrastructure operators. Their routing and commercial relationships can influence the path as much as physical distance.
Internet exchange points are physical interconnection sites where networks exchange traffic. Local peering can keep paths closer and reduce dependence on distant transit. However, the presence of a nearby exchange point does not guarantee that every player’s ISP uses it efficiently, so actual routes still need testing.
A community can compare candidate locations using representative players or probes placed near its main geographic clusters. The comparison should include:
- Average and peak latency
- Jitter during active sessions
- Packet-loss frequency
- Route changes and unexpected detours
- Performance during peak usage hours
- Stability across the ISPs commonly used by players
Traceroutes can help identify indirect paths, while longer monitoring periods show whether an issue is temporary or recurring. Synthetic probes provide useful baseline data, but feedback and measurements from real players are especially valuable because they reflect the residential networks the community actually uses.
Matchmaking can balance waiting time and connection quality
Route testing also reframes matchmaking. The fastest possible match is not always the best result if it places one or more participants on a server with excessive latency.
AWS documents placement policies that progressively relax latency limits when a session cannot meet stricter requirements immediately. This allows a system to balance waiting time against a defined session-quality standard.
A community can apply the same principle even without a complex automated system. For example, it might initially search for a server location where every player remains under a preferred latency threshold. If no suitable session is available after a set period, the acceptable limit can be increased gradually.
This approach gives organizers control over the trade-off. Competitive groups may prefer longer waits to protect responsiveness, while casual communities may accept higher latency to start playing sooner. The important point is that the compromise is deliberate rather than an unnoticed consequence of poor placement.
Population size must also be considered. Splitting a small community across too many regions can produce half-empty servers and longer queues. A single well-connected location may therefore deliver a better overall experience, even if it is not the closest option for every participant.
Regions, availability zones, and nearby capacity
Clear terminology prevents a hosting plan from becoming a simple geography exercise. A region, an availability zone, and an edge or local location serve different purposes.
AWS Regions are broad geographic locations, while AWS Availability Zones are isolated infrastructure locations within a Region. Availability Zones help applications remain resilient to local infrastructure failures, but they are not intended primarily as separate global player locations.
AWS Local Zones extend selected services closer to end users and support low-latency workloads such as real-time gaming and AR/VR. They can provide nearby compute capacity without requiring the entire application architecture to operate independently in another full Region.
Azure regions similarly contain one or more data centers connected by high-capacity, fault-tolerant, low-latency networks. Availability zones provide separated infrastructure groups for fault isolation and resilience.
These distinctions matter because resilience and player proximity solve different problems. Deploying across availability zones can improve service continuity within a region, while operating in multiple regions or nearby local locations can improve latency for geographically separated player groups.
The correct architecture may use both. A community platform could run resilient backend services across availability zones while placing latency-sensitive game sessions closer to active players.
When is a single server location enough?
A basic single-location virtual server may suit a community when most players are concentrated in one region, the game has moderate resource demands, and the selected provider offers stable routes to the relevant ISPs.
This setup is usually easier and less expensive to manage. It also keeps players in one matchmaking pool and avoids the operational work involved in synchronizing several locations.
However, its fit depends on more than geography. Organizers should consider:
- CPU performance and available processing headroom
- Memory requirements for the game, world, and plugins
- Network throughput and connection limits
- Expected simultaneous player count
- Storage performance and backup requirements
- The game’s latency tolerance and networking model
- Whether resources are shared or dedicated
An empty server is not a useful performance test by itself. The environment should be tested with a realistic player count, typical maps or worlds, and the same mods, plugins, or background services planned for normal operation.
Monitoring CPU usage, memory consumption, network throughput, tick rate, and response times under load helps reveal whether the server has enough headroom for busy sessions.
When does multi-location hosting make sense?
Multi-location deployment becomes useful when player measurements show stable demand across distant geographic clusters that cannot be served adequately from one location.
For example, a community with active groups in North America and Europe may find that a single server produces acceptable but uneven performance. Separate regional servers could lower latency for both groups, provided each region has enough players to support healthy sessions.
Multi-location infrastructure also introduces additional decisions. Organizers may need to determine how players are assigned to regions, whether progress and account data are shared, how matchmaking pools are managed, and what happens when one location becomes unavailable.
The added cost is worthwhile only when it solves a measured problem. Deploying more locations because they appear impressive on a provider’s coverage map can create unnecessary complexity without improving the actual experience.
A gradual approach is usually more practical. Start with the location that offers the best balance for the current community, monitor real sessions, and add capacity where the data shows persistent demand or unacceptable performance.
Immersive sessions raise the planning bar
VR and AR multiplayer place stricter demands on server placement and network behaviour. Synchronized movement, voice, interactive objects, and streamed or rendered media can make latency variation and packet loss more noticeable.
A delayed action in a traditional game may be frustrating, but a mismatch between physical movement and a virtual environment can immediately break immersion. Sudden latency spikes may cause objects or avatars to shift unexpectedly, while packet loss can disrupt voice communication or state updates.
AWS lists real-time gaming and AR/VR among Local Zone use cases, while technical guidance identifies latency, jitter, packet loss, and bandwidth as important quality-of-experience factors.
Bandwidth becomes especially relevant when the system streams rendered media rather than exchanging only game-state data. Each participant may require a continuous high-quality video stream, increasing both network and compute demands. GPU availability, encoding performance, and concurrent session limits can then become part of the hosting decision.
The server should be tested under realistic conditions, including the expected number of simultaneous users and the actual type of traffic generated by the application. A location that performs well for a small technical test may struggle when many immersive sessions begin at once.
Can traditional VPS hosting support immersive multiplayer?
Traditional VPS hosting is not automatically ruled out by immersive multiplayer. Its suitability depends on the workload design, available compute resources, network quality, concurrency, and placement.
A VPS may be sufficient when the application exchanges lightweight state information, serves a small number of users, and does not require intensive rendering. Strong CPU performance, adequate memory, predictable networking, and a suitable location can support many community-hosted multiplayer workloads.
More demanding services may require dedicated CPU resources, GPU access, or dedicated hardware. Shared virtual resources can create unpredictable performance if other workloads on the physical host compete for processing time or network capacity.
The hosting category matters less than whether the available resources match the application. Organizers should define their expected workload, test it under load, and compare results with acceptable session-quality thresholds.
Upgrading hardware will not correct a poor network route, just as moving to a closer server will not solve CPU saturation. Hosting decisions need to address both network quality and processing capacity.
Monitoring turns placement into an ongoing process
A hosting location that works today may not remain the best option indefinitely. Player distribution can change as the community grows, while network providers can adjust routes, peering relationships, and transit arrangements.
Ongoing monitoring should track latency, jitter, packet loss, server load, session concurrency, and player complaints. Changes should be examined by location and ISP where possible because a problem affecting one network may not appear in the overall average.
Organizers should also review whether active player clusters are shifting. A growing group in another region may eventually justify a second deployment, while declining activity could make an existing location unnecessary.
This turns hosting into a continuous planning process:
- Measure where active demand originates.
- Test realistic routes to candidate locations.
- Deploy the simplest setup that meets the group’s needs.
- Monitor network and server performance during real sessions.
- Adjust placement or capacity when repeated evidence supports a change.
The useful direction is a monitored design shaped by actual sessions rather than assumptions. The marketplace gives a group quick access to an appropriate game purchase before it meets, while careful infrastructure planning determines whether everyone can enjoy a stable shared experience.
